
What is GLM-5.3-Flash?
GLM-5.3-Flash is Z.ai's native multimodal model, released on 2026-08-26. The stealth preview Ox Alpha was this model. It accepts text, images, and video, returns text, and holds a 1,048,576-token context.
TL;DR — As of 2026-10-09, Z.ai shipped GLM-5.3-Flash on 2026-08-26. The stealth preview Ox Alpha was this model. It accepts text, images, and video and returns text, with a 1,048,576-token context. Z.ai lists $0.15 input / $0.50 output per million tokens. Reasoning stays on. It is a coding and long-task model. It does not file a searchable recap of a long video.
Paste a podcast, lecture, or meeting URL — BibiGPT turns it into chapters, a transcript, and follow-up Q&A.
As of 2026-10-09, Z.ai released GLM-5.3-Flash on 2026-08-26. Ox Alpha was this model. Text, image, and video in; text out; 1,048,576-token context. Z.ai lists $0.15 / $0.50 per million tokens. Reasoning stays on. A coding and long-task model, not a summary engine.
Public facts from the GLM-5.3-Flash model card — not a claim that BibiGPT runs this model.
The stealth preview called Ox Alpha was revealed as Z.ai GLM-5.3-Flash. The named release date is 2026-08-26. The free preview under the old name has ended.
GLM-5.3-Flash is a native multimodal model. It accepts text, images, and video and returns text. The context window is 1,048,576 tokens. Reasoning stays on and cannot be turned off; the default effort is max.
On the public model card as of 2026-10-09, Z.ai posts $0.15 input and $0.50 output per million tokens. Other hosts post different rates, including discounts below that card. Those are host prices, not a BibiGPT plan.
A coding and long-task model does not timestamp last week's lecture. Knowledge work still needs a file you can search next Tuesday.
GLM-5.3-Flash is positioned for efficient coding and long-horizon agent tasks. After the recording exists, you still need chapters, a transcript, and a quote you can find again. That job is async.
Laxis State of Meetings 2026: knowledge workers sit through 21.7 meetings a week, about 30% of the work week. A cheaper token does not shrink that pile. A timestamped recap does.
Edison Infinite Dial 2026: US podcast listeners average 8 hours 24 minutes a week across 6.8 shows. The leftover episodes need a triage desk, not another model card. A summary decides which hour is worth playing.
Headline facts from the public GLM-5.3-Flash model card, checked 2026-10-09.
Z.ai shipped GLM-5.3-Flash as a named model. Model id on the public card: z-ai/glm-5.3-flash.
The stealth preview Ox Alpha was revealed as GLM-5.3-Flash. The free preview under the old name has ended.
Native multimodal input, text output, 1,048,576-token context. Reasoning stays on and cannot be disabled. Default effort is max.
As of 2026-10-09, Z.ai posts $0.15 input and $0.50 output per million tokens. Other hosts post different rates, including discounts. Host prices, not a BibiGPT plan.
The card positions GLM-5.3-Flash for efficient coding and long-horizon tasks. After a lecture or podcast exists as a file, you still need chapters you can search next week. That is the BibiGPT path, not a GLM-5.3-Flash integration.
Where a long-context model helps — and where a notes workflow still does the work.
US listeners average 8 hours 24 minutes a week across 6.8 shows (Edison Infinite Dial 2026). A model card does not triage the backlog. Generate chapters first, then decide which hour is worth a full listen.
Laxis 2026: 21.7 meetings a week, about 30% of the work week. A cheaper token is useful on a knowledge-work task. Next Tuesday you still need the sentence that was decided. File the recording; search the transcript.
Paste the URL. Get chapters before you press play, jump to a timestamp, export Markdown. GLM-5.3-Flash does not have to be in the loop. The notes workflow already runs on files you own.
The notes workflow is the product. This page owns the 2026-08-26 event.
Launch claims come from the public model card. Last updated 2026-10-09. Not an integration claim.
GLM-5.3-Flash was released on 2026-08-26. It is a native multimodal model from Z.ai, suited to efficient coding and long-horizon agent tasks. It accepts text, images, and video and returns text. Context window: 1,048,576 tokens. The stealth model Ox Alpha was this model. Reasoning stays on and cannot be disabled; efforts low, high, and max are supported, and max is the default.
OpenRouter — Z.ai GLM 5.3 Flash model card (checked 2026-10-09) ↗Z.ai posts $0.15 input and $0.50 output per million tokens on that card. Other hosts post different rates, including discounts below the Z.ai card. The blended average a buyer pays is not the same number as the Z.ai list.
OpenRouter — Z.ai GLM 5.3 Flash model card, provider table (checked 2026-10-09) ↗US podcast listeners average 8 hours 24 minutes a week and follow 6.8 shows. The leftover catalog needs a triage desk, not another model card.
Edison Research — The Infinite Dial 2026 (as of 2026-03) ↗Knowledge workers attend 21.7 meetings a week, about 30% of the work week (Laxis State of Meetings 2026, as of 2026-01).
Laxis — State of Meetings 2026 ↗GLM-5.3-Flash is Z.ai's native multimodal model, released on 2026-08-26. The stealth preview Ox Alpha was this model. It accepts text, images, and video, returns text, and holds a 1,048,576-token context.
Why people use BibiGPT to turn videos into text every day.
Trusted by 50,000+ users worldwide
“I paste a link and get clean captions in seconds — it saves me hours of retyping every single week.”
Maya R.
Content Creator · Repurposes short videos
“Exporting the transcript lets me review new words at my own pace instead of pausing the video constantly.”
Daniel K.
Language Learner · Studies with real videos
“Accurate, timestamped text I can quote directly. It has quietly become part of my daily workflow.”
Priya S.
Researcher · Cites public talks
FAQ'S
Ask us anything!
 1
Install a video-summary skill into DeepSeek Harness in one copy-paste — SKILL.md matches Claude Code. Or skip dsh: paste a Bilibili or YouTube link in the browser and get a timestamped summary.
 2
Best Bilibili AI video summary tool 2026? Compare 5 options, then paste a Bilibili link for a free AI recap, mind map, and transcript-style takeaways — no login needed.
 3
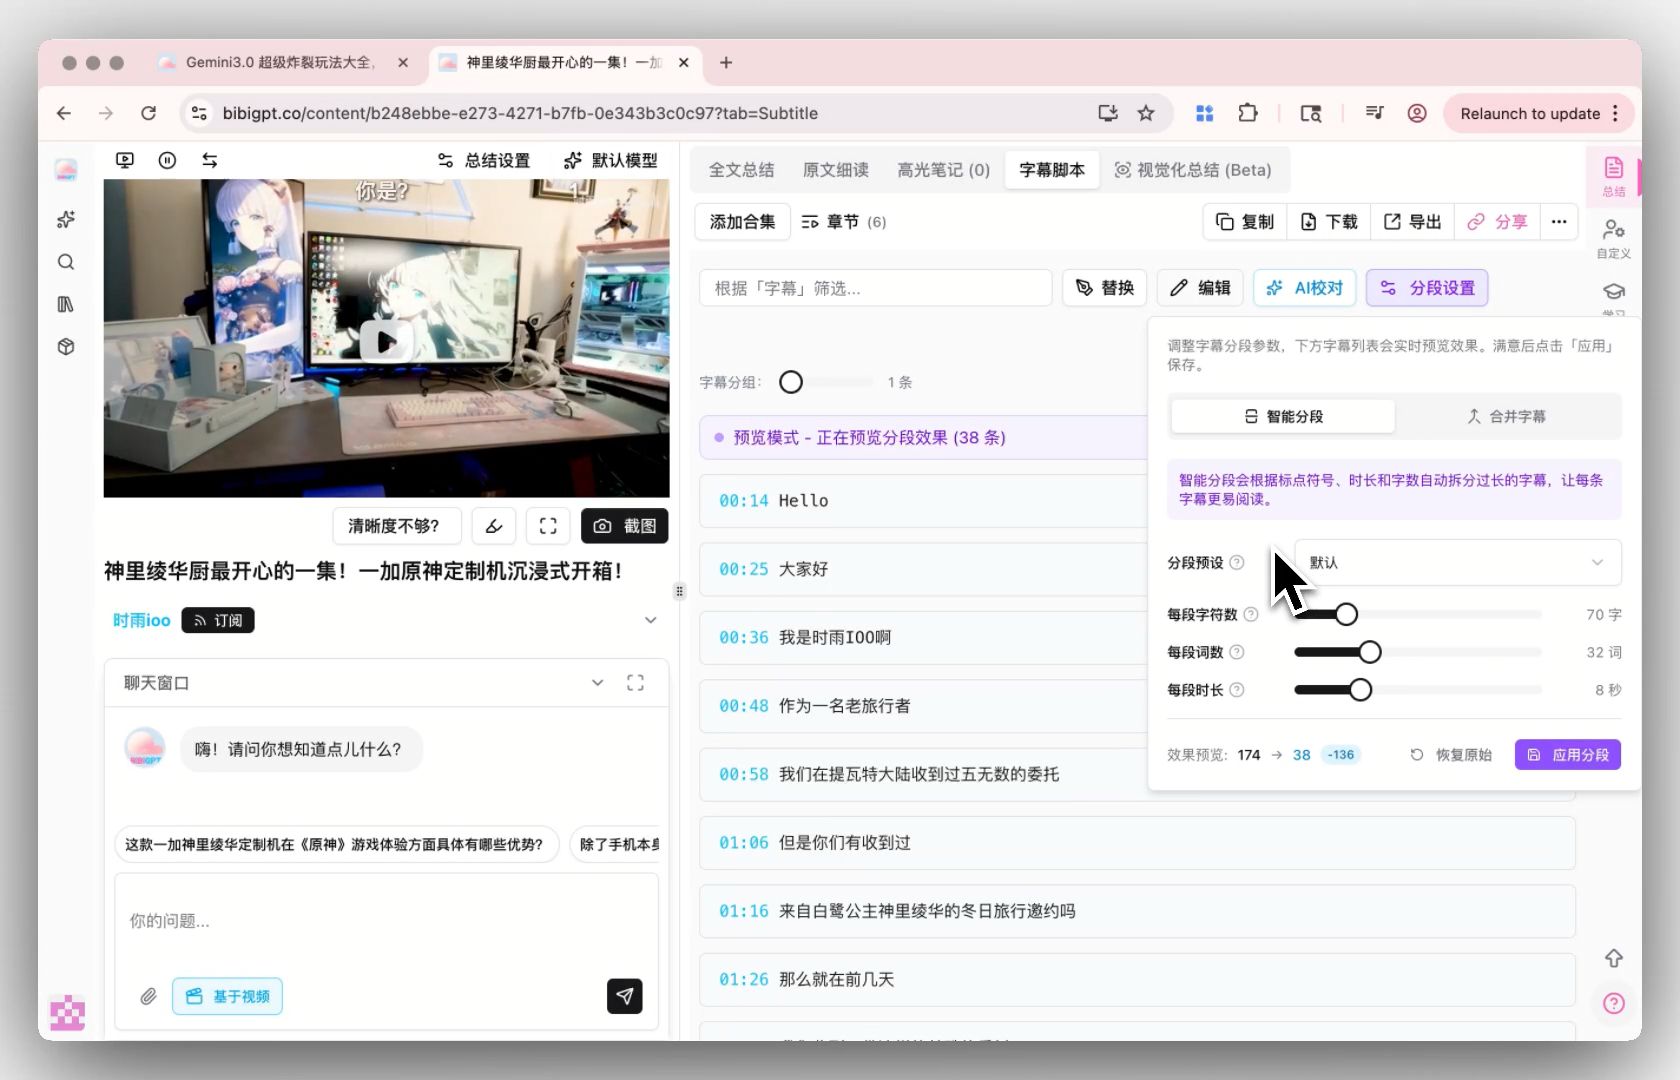
Extract Bilibili subtitles free: paste a BV/av link for a transcript even with no captions. Compare 5 tools for SRT export and AI summary. No signup to start.
Paste a podcast, lecture, or meeting recording into BibiGPT. You get chapters, a searchable transcript, and follow-up Q&A. GLM-5.3-Flash is Z.ai's multimodal model for coding and long tasks. The notes still need a timestamp.